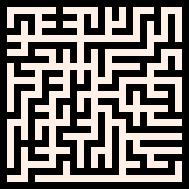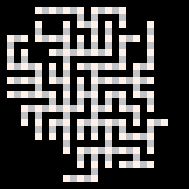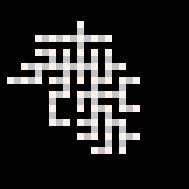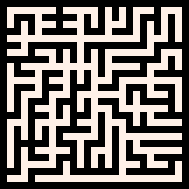
MarkovJunior is a probabilistic programming language where programs are combinations of rewrite rules and inference is performed via constraint propagation. MarkovJunior is named after mathematician Andrey Andreyevich Markov, who defined and studied what is now called Markov algorithms.


In its basic form, a MarkovJunior program is an ordered list of rewrite rules. For example, MazeBacktracker (animation on the left below) is a list of 2 rewrite rules:
RBB=GGRor "replace red-black-black with green-green-red".RGG=WWRor "replace red-green-green with white-white-red".
On each execution step MJ interpreter finds the first rule in the list that has a match on the grid, finds all matches for that rule and applies that rule for a random match. In the maze backtracker example, interpreter first applies a bunch of RBB=GGR rules. But eventually the green self-avoiding walk gets stuck. At this point the first rule has no matches, so interpreter applies the second rule RGG=WWR until the walk gets unstuck. Then it can apply the first rule again, and so on. Interpreter stops when there are no matches for any rule.


Probabilistic inference in MarkovJunior allows to impose constraints on the future state, and generate only those runs that lead to the constrained future. For example, inference in Sokoban rules {RWB=BRW RB=BR} makes a group of (red) agents organize (white) crates into specified shapes.
Using these ideas, we construct many probabilistic generators of dungeons, architecture, puzzles and fun simulations.

Additional materials:
- Xml syntax overview.
- Higher resolution screenshots and more seeds: ModernHouse, SeaVilla, Apartemazements, CarmaTower, Escheresque, PillarsOfEternity, Surface, Knots.
- Unofficial technical notes by Dan Ogles and code documentation by Andrew Kay.
A Markov algorithm over an alphabet A is an ordered list of rules. Each rule is a string of the form x=y, where x and y are words in A, and some rules may be marked as halt rules. Application of a Markov algorithm to a word w proceeds as follows:
- Find the first rule
x=ywherexis a substring ofw. If there are no such rules, then halt. - Replace the leftmost
xinwbyy. - If the found rule was a halt rule, then halt. Otherwise, go to step 1.
For example, consider this Markov algorithm in the alphabet {0, 1, x} (ε is the empty word):
1=0x
x0=0xx
0=ε
If we apply it to the string 110 we get this sequence of strings:
110 -> 0x10 -> 0x0x0 -> 00xxx0 -> 00xx0xx -> 00x0xxxx -> 000xxxxxx -> 00xxxxxx -> 0xxxxxx -> xxxxxx
In general, this algorithm converts a binary representation of a number into its unary representation.
Markov's student Vilnis Detlovs proved that for any Turing machine there exists a Markov algorithm that computes the same function. In comparison, grammars are unordered sets of rewrite rules and L-systems are rewrite rules that are applied in parallel. For more interesting examples of Markov algorithms check Markov's book or see the greatest common divisor example in the comment section or multiplication example on Wikipedia.
How would one generalize Markov algorithms to multiple dimensions? First, in multiple dimensions there are no natural ways to insert a string into another string, so the lefts and rights of our rewrite rules should have the same size. Second, there are no natural ways to choose the leftmost match. Possible options are:
- Choose a random match. This is what MJ's
(exists)nodes do. - Choose all matches. There is a problem with this option however because different matches can overlap and have conflicts. Possible solutions are:
- Greedily choose a maximal subset of non-conflicting matches. This is what MJ's
{forall}nodes do. - Consider all matches in superposition. That is, instead of separate values, keep waves in each grid cell - boolean vectors that tell which spacetime patterns are forbidden and which are not. And this is how MJ performs inference.
- Greedily choose a maximal subset of non-conflicting matches. This is what MJ's
We lose Turing completeness because our new procedure is not deterministic, but practice shows that this formalism still allows to describe a huge range of interesting random processes.
The simplest MarkovJunior program is probably (B=W). It contains just a single rule B=W. On each turn, this program converts a random black square into a white square.


(B=W) | (WB=WW) | (WBB=WAW) | (WBB=WAW)
Growth model (WB=WW) is more interesting. On each turn it replaces a black-white pair of adjacent cells BW with a white-white pair WW. In other words, on each turn it picks a random black cell adjacent to some white cell and color it into white. This model is almost identical to the Eden growth model: on each turn both models choose among the same set of black cells. They differ only in probability distributions: a uniform distribution over black cells adjacent to white cells is not the same as a uniform distribution over pairs of adjacent black and white cells.
Model (WBB=WAW) generates a maze, with a single line of code! Compare it with an implementation in a conventional language. Any MarkovJunior model can be run in any number of dimensions without changes. On the right you can see the end result of MazeGrowth in 3d, rendered in MagicaVoxel. By default, we use PICO-8 palette:

Model (RBB=WWR) is a self-avoiding random walk. Note that self-avoiding walks in 3d are longer on average than in 2d. In general, comparing the behaviors of similar random processes in different dimensions is a fascinating topic. A classic result of George Pólya says that a random walk in 2d returns to its initial position with probability one, while in 3d this is no longer the case.


(RBB=WWR) | LoopErasedWalk | (RB=WR RW=WR)
We can put several rules into one rulenode. For example, (RBB=WWR RBW=GWP PWG=PBU UWW=BBU UWP=BBR) is a loop-erased random walk. Trail model (RB=WR RW=WR) generates decent connected caves.
Model (RBB=WWR R*W=W*R) is known as the Aldous-Broder maze generation algorithm. The wildcard symbol * in the input means that any color is allowed to be in the square. The wildcard symbol in the output means that the color doesn't change after the application of the rule. Aldous-Broder algorithm takes much more turns on average to generate a maze than MazeGrowth, for example, but it has a nice property that MazeGrowth doesn't have: each maze has the same probability to be generated. In other words, MazeTrail is an unbiased maze generation algorithm, or it samples mazes (or spanning trees) with the uniform distribution. Wilson's algorithm is a more efficient unbiased maze generation algorithm. Compare its MarkovJunior implementation with an implementation in a conventional language!
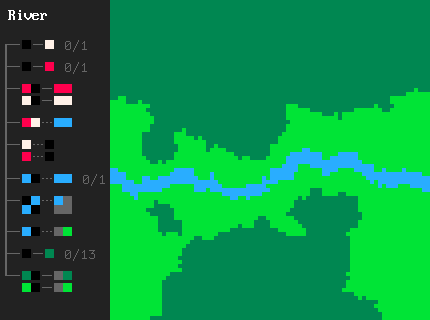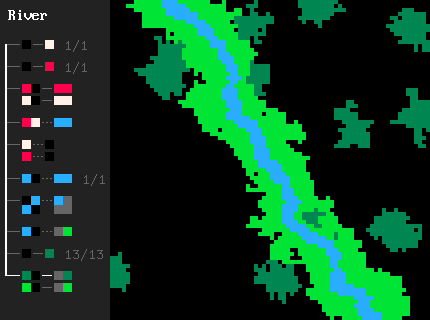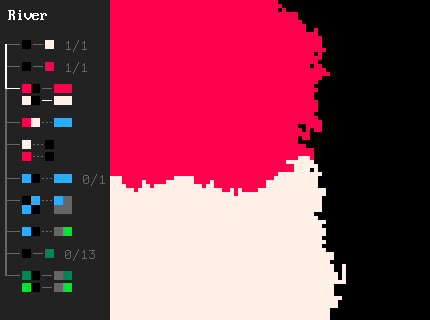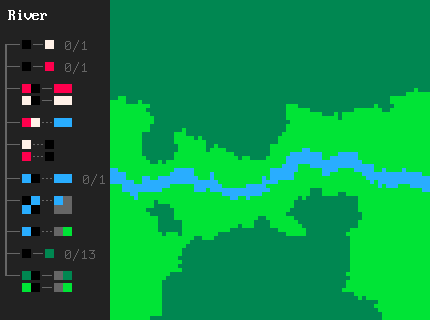
We can put several rulenodes into a sequence node, to be run one after the other. In the River model we first construct a stochastic Voronoi diagram with 2 sources, and use the boundary between the formed regions as a base for a river. Then we spawn a couple more Voronoi seeds to grow forests and simultaneously grow grass from the river. As a result, we get random river valleys!


In Apartemazements we start with a WFC node and then do constructive postprocessing with rulenodes:
- Prepare constraints: mark bottom cells with a separate bottom color, mark the remaining border cells (sides and top) with a separate border color. Border cells should map to Empty, bottom cells should map to all tiles except Down.
- Run WFC Paths tileset to generate closed stairy cycles.
- Randomize light sources.
- Drop columns from corners of flat tiles.
- Retract double columns, columns that touch ground and columns that touch stairs, except columns growing from corners of the Turn tiles.
- Grow windows between neighboring columns.
- Merge windows into bigger rectangles. We do this in several steps:
- Detect uneven patterns of windows when window corners touch window midpoints.
- Mark these patterns and propagate the markings through the whole lengths of window sides.
- Merge unmarked pairs of window sides.
- Turn the remaining 1x1 windows into walls.
A more interesting way to combine nodes is to put them into a Markov node. Markov nodes substantially expand what we can do, because they allow to return to past nodes. When a Markov node is active, interpreter finds its first child node that matches and applies it. On the next turn, it finds the first matching node in the list again, and so on. The simplest example of the Markov node use is MazeBacktracker explained in the top section.


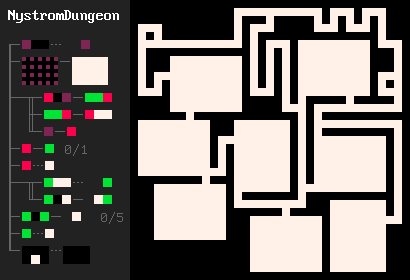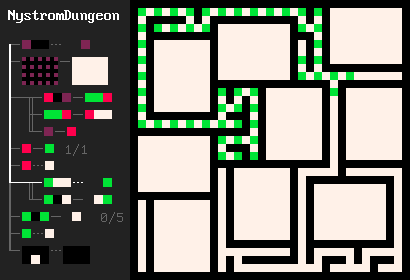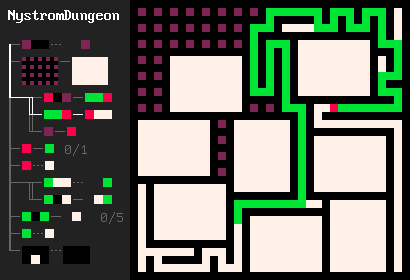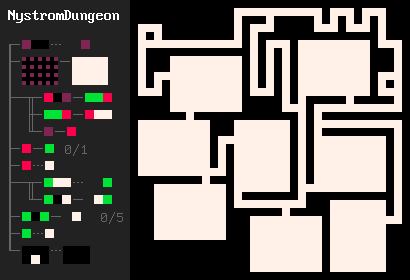
One of my favorite examples that motivated the development of MarkovJunior is Bob Nystrom's dungeon generation algorithm. It goes as follows:
- Draw a grid
{PBB=**P}. - Spawn a bunch of rooms
(room.png). - Generate a maze on the rest of the grid. We can use any maze generation algorithm, but MazeBacktracker is preferred because it produces fewer branching points.
- Make the resulting configuration of rooms and corridors connected. This can be elegantly done with a Markov node
({GWW=**G}(GBW=*WG)). - Make some additional connections
(GBG=*W* #5), so the resulting dungeon has cycles. Dungeons without cycles are pretty boring, since the player has to return through already explored zones. - Retract dead ends
{BBB/BWB=BBB/BBB}.


Like in REFAL, Markov nodes can be nested: once we go into a child node, we ignore outer nodes until the child branch completes.
Probabilistic inference in MarkovJunior allows to impose constraints on the future state, and generate only those runs that lead to the constrained future. In other words, inference connects 2 given states (or partially observed states) with a chain of rewrite rules.
The simplest example of inference use is connecting 2 points with a path. In the self-avoiding walk model (RBB=WWR) we can observe a given square on the grid to become R red. Then the interpreter would generate only those walks that lead to the observed square. We can set the interpreter to follow the goal more strictly or less strictly by varying the temperature parameter. By default, temperature is set to zero.


Coldest | Cold | Hot | Hottest
Another thing we can do is to observe all odd grid squares becoming white or red. Then the interpreter would generate self-avoiding walks that cover the entire grid.


We can engage inference for any rewrite rules. For example, inference for stair-drawing rules connects 2 points with a stairy path. Inference for rule R**/**B=B**/**R generates paths that a chess knight can take. Inference in the CrossCountry model connects 2 points with a path taking terrain costs into account. Inference for the Sokoban ruleset {RB=BR RWB=BRW} solves Sokoban puzzles or even multiagent Sokoban puzzles!

Inference in MarkovJunior is done via unidirectional (fast) or bidirectional (slow, but more powerful) constraint propagation. Unidirectional constraint propagation for rewrite rules can be described equivalently in terms of rule propagation fields which generalize Dijkstra fields for arbitrary rewrite rules. Dijkstra fields is a popular technique in grid-based procedural generation (1, 2, 3). They in turn generalize distance fields used in computer graphics.
If constraint propagation completes it doesn't necessarily mean that the goal state is achievable. But if the propagation fails then we know for sure that the goal is not achievable. This allows to catch states where a crate is pushed to the wrong wall in Sokoban, or where the grid-covering walk splits the grid into 2 disconnected parts. In addition to this boolean heuristic, it's worth looking at the minimal number of turns required for constraint propagation to complete. This integer-valued heuristic is admissible, and we use it in A* search to sample paths made of rewrite rules between 2 given states.
- Program synthesis for procedural generation. William Chyr's talk "Level Design in Impossible Geometry" is not at all about procedural generation, yet I find one slide to be very characteristic for pcg practice. William compares his earlier and later approaches to level design. The earlier one produced chaotic levels, while the later approach produced more structured, more intentional levels based on one central idea. Later levels weren't simpler, yet they were more memorable and easier for players to perceive. To me, the left level looks like it was generated procedurally! It has a very similar feel to my procedural voxel puzzles. Can we make generators that produce levels that are more like the one on the right? This problem may seem AI-complete. But I'd argue it is very similar to classic genetic programming problems like Koza's lawnmower problem. For example, take a simple procgen task of generating Hamiltonian paths on the grid. Even for small grid sizes like 29x29 this task is already computationally demanding. But do we really need to sample from all possible paths in practice? If we give this task to a human, they would probably draw a spiral or a zigzag curve - these are much more memorable and intentional designs than a random Hamiltonian path, plus they generalize to any grid sizes. To summarize, we can ask the system either to find a random Hamiltonian path or to find a short program that generates Hamiltonian paths. In the first case the result would look like the left level on the slide, and in the second case like the right level. Solving the latter program synthesis problem would create more memorable and intentional generators.
- Model synthesis from examples. Markov algorithms seem to be a perfect environment for program/model synthesis: no variables, ifs or whiles, nodes can be easily moved around without breaking correctness, models are easy to make differentiable. Random MJ programs are often fun and can produce human-relatable results and behaviors.
- Can we synthesize a MJ model from a result, or a set of results?
- Given a maze, is it possible to determine (or assign probabilities) whether it was generated by MazeGrowth or MazeBacktracker?
- Solve the Abstraction and Reasoning Challenge by inferring MarkovJunior models. Adjoint problem: use insights from the ARC challenge to build a better DSL for procedural generation on a grid.
- Custom algorithms that run in the wave space. To unite the advantages of constructive and constrained-based procedural generation. Related: custom algorithms (MJ rewrite rules) with custom energy functions like Ising energy or ConvChain energy.
- Generalize the notion of a pattern.
- Investigate MJ-like processes on other (possibly nonregular) grids or arbitrary graphs.
- Experiment with interactive extensions of Markov algorithms. It's possible to turn any MJ model into a game by assigning specific rewrite rules or nodes to key presses.
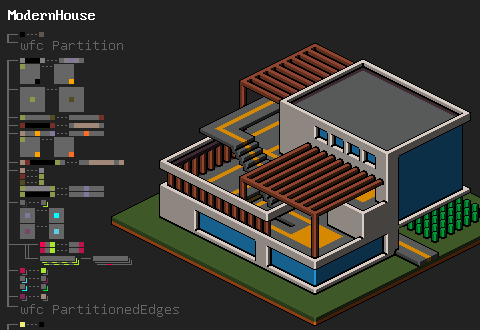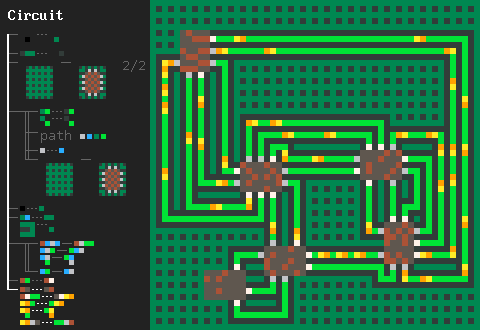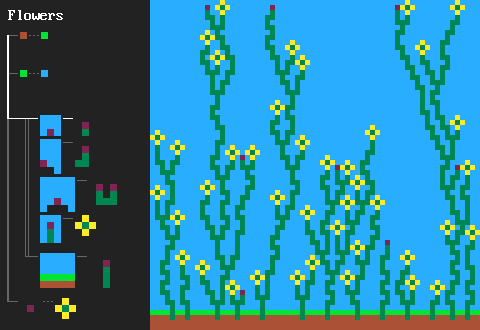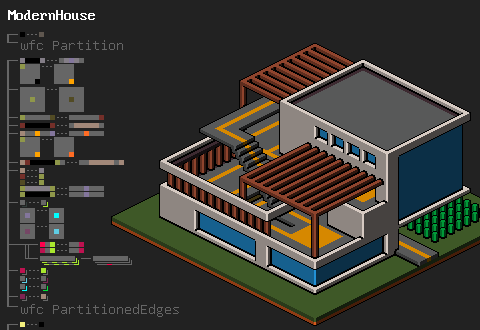
- Push the state of the art in grid-based procedural generation. ModernHouse does not yet reach the structural variety of human-designed houses like Sims 2 houses. Use more subtle constraints.
Compared to Turing machines and lambda calculus, Markov algorithms is probably the shortest and simplest way to rigorously define what an algorithm is.
Exercise: prove that the following Markov algorithm finds the greatest common divisor of 2 numbers written in a unary representation. For example, if we apply it to 111111*1111111111 we get 11.
1a=a1
1*1=a*
1*=*b
b=1
a=c
c=1
*=ε (halt)
Fast pattern matching. MarkovJunior interpreter samples matches uniformly, but it doesn't scan the whole grid every turn. To keep pattern matching fast, the interpreter remembers previously found matches and searches only around the places that got changed. When a rulenode is encountered for the first time, MJ interpreter uses a multidimensional version of the Boyer–Moore algorithm.
Stochastic relaxation. Markov nodes have a very nice representations as limits of differentiable nodes. Consider an unordered set of rewrite rules where each rule r is assigned a weight w(r). On each step the interpreter finds all matches for all rules and chooses a random match according to the Boltzmann distribution p(r) ~ exp(-w(r)/t). Then in the freezing limit t->0 we get a Markov node, ordered by weights. What's good about this construction, is that for any t>0 and for a typical score function, score's average on multiple runs would be a continuous (and smooth for practical purposes) function of weights. This means that one can find the optimal weights by gradient descent and then freeze the system to get the final discrete program.
Read this essay by Boris Kushner about A. A. Markov and his work in constructive mathematics.
Main used work:
- Andrey A. Markov, The Theory of Algorithms, 1951. Markov used these ideas earlier in 1947 in his proof of the algorithmic undecidability of the word problem in semigroups. See also a later book with a more detailed treatment. I would be grateful for links to English translations in open access.
- Guilherme S. Tows, Imagegram, 2009. MarkovJunior takes forall-nodes from Imagegram.
- Valentin Turchin, REFAL language, 1968. MJ takes the idea of nested Markov nodes from REFAL.
- Brian Walker et al., The incredible power of Dijkstra maps, 2010. A discussion in the the roguelike community that contains many techniques of using Dijkstra maps/distance fields for procedural generation and NPC AI. Later writeups: 1, 2. We generalize Dijkstra maps to arbitrary rewrite rules.
- Pavlos S. Efraimidis, Paul Spirakis, Weighted Random Sampling, 2005.
- Work used in custom nodes: Model Synthesis, Wave Function Collapse Algorithm, ConvChain Algorithm.
- Classic algorithms: constraint propagation, constraint solving algorithms, graph traversal, A* search.
Related work:
- Daniel Ritchie, Probabilistic Programming for Procedural Modeling and Design, 2016.
- Lingfeng Yang, From Execution Traces to Specialized Inference, 2015.
Sources of examples:
- BasicKeys and Keys are adaptations of graph grammars formulated by Joris Dormans, Engineering Emergence: Applied Theory for Game Design, 2012. Which in turn are development of the earlier work by David Adams, Automatic Generation of Dungeons for Computer Games, 2002. I use a variation of these models to generate key-lock-bridge puzzles in SeaVilla.
- CarmaTower is a proceduralization of a voxel scene by Antoine Lendrevie.
- The NystromDungeon model is a MarkovJunior port of Bob Nystrom's dungeon generator.
- HamiltonianPath algorithm is adapted from this article. Compare it with an implementation in a conventional language.
- Room shapes in DungeonGrowth are taken from the r/proceduralgeneration post. Note that MJ interpreter automatically performs the optimizations described in the post.
- The Wilson model is a rewrite rule formulation of the Wilson's algorithm. Compare it with an implementation in a conventional language.
- MazeGrowth model is also known as maze generation via random traversal. Compare it with an implementation in a conventional language.
- Growth is closely related to the Eden growth model.
- BernoulliPercolation is a well studied model in a percolation theory.
- NestedGrowth is taken from Imagegram.
- SmoothTrail is adapted from 128_mhz's tweet.
- SokobanLevel1 seems to be the first level from Hiroyuki Imabayashi's Sokoban puzzle. SokobanLevel2 is the level 452 from Ionic Catalysts XI set.
- RainbowGrowth was proposed by mure.
- MultiHeadedWalk, MultiHeadedDungeon and MultiHeadedWalkDungeon are based on the idea by Ilya Kudritsky.
- Island model is by Guillaume Fiette.
- LostCity, Forest and Texture models are based on the model by Andrew Kay.
- Division and Rosettes models were developed by scorpion451.
Voxel scenes were rendered in MagicaVoxel by ephtracy. Special thanks to Brian Bucklew for demonstrating the power of Dijkstra fields to me in roguelike level generation and Kevin Chapelier for a number of good suggestions. The font used in GUI is Tamzen.
MarkovJunior interpreter is a console application that depends only on the standard library. Get .NET Core for Windows, Linux or macOS and run
dotnet run --configuration Release MarkovJunior.csproj
To build the application without running it, run
dotnet publish --configuration Release MarkovJunior.csproj
After this, a self-contained app will appear in the bin/publish folder. Run MarkovJunior.exe, and it will put all the generated artifacts in the output folder.
Alternatively, download and run the latest release for Windows.
Generated results are put into the output folder. Edit models.xml to change model parameters. Open .vox files with MagicaVoxel.
- Yuu made a TypeScript version of MarkovJunior that runs on the web, extended the language and added the ability to bind nodes to keypresses.
- Aseaday is porting MarkovJunior to JavaScript.
- Andrew Kay added XML documentation to C# source code.
- Dan Ogles wrote MarkovJunior technical notes with the focus on fields and inference.
- Andrew Kay designed MJr, a compiled language based on pattern rewriting.
- Ashley is writing a Rust implementation of MarkovJunior as a Python library.
- LMCuber is porting MarkovJunior to Python.
- William Manning developed a Julia implementation of MarkovJunior that runs in any number of space dimensions.
MarkovJunior development was funded by